
Robots.txt for AI: decide if models train on your site
Google plans to honour a shared robots.txt signal in 2027 that says whether your site can be used to train AI. What changes and how to decide what to open up.
Blog · · 6 min · digizone team
Robots.txt for AI is about to get simpler: Google has announced that, together with other artificial intelligence providers, it aims to honour a shared signal in 2027 that lets any website say, in a single rule, whether its content may be used to train models. For a business with its own website, the question stops being a technical one and becomes a commercial one: which parts of your site do you want models to learn from, and which not?
In short
- On 30 October 2026, Google announced that it aims to honour, alongside other AI providers in 2027, a shared robots.txt signal that lets a website say whether its content may be used to train AI.
- The signal is called __usage_ai-training and comes from an individual draft submitted to the IETF by Kevin Kelley of Anthropic: it is a preference, not an obligation, and it is not yet a standard.
- According to Google, opting out of training via Google-Extended does not remove a site from its search engine, but it may keep it out of linked answers in the Gemini app.
- The useful step today is to separate the parts of your site that are a shop window from the parts that are your product, decide for each, and put anything you do not want to share behind a login.
What changes with robots.txt for AI
On 30 October, Google explained on its blog for website owners that it plans to support a shared AI training control in robots.txt, the text file at the root of every website that gives instructions to the bots that crawl it. The proposal builds on work from the IETF's AIPREF working group; the IETF is the body behind many of the internet's standards. Google says it aims to support it alongside other AI providers in 2027, and its crawler documentation narrows that down to early 2027.
Today, anyone who wants to opt out of training has to write a rule for each company, as heise points out: GPTBot for OpenAI, ClaudeBot for Anthropic or Google-Extended for Google, among others. The shared signal uses a single name, __usage_ai-training, defined in a draft submitted to the IETF the same day by Kevin Kelley of Anthropic. It adds no new syntax: it is written like any other robots.txt rule and lets you, for example, say no to training across the whole site except the press area.
Three caveats apply. The draft is an individual proposal which, by its own account, has no formal standing at the IETF yet. Nor does it bind anyone: it expresses a preference, and the draft itself accepts that a private agreement may override it. And it does not replace each company's own rules: according to Google, those will keep working, so you can set a general choice and fine-tune it for a particular provider.
Free recipes, paid courses and a nagging doubt
Imagine Teresa runs a cookery school with two chefs. Every week she posts a free recipe on her website, with photos she takes herself on her phone, and she sells video courses in a members' area. The recipes bring in visitors; the courses pay the bills.
One Tuesday, a student tells her that an AI assistant gave her a rice recipe that looks a lot like Teresa's. Teresa has no idea whether it is a coincidence. Her nephew tells her to block everything and forget about it. But she also wants her school to come up when someone asks an assistant about cookery courses in her city. And she does not know whether one rules out the other.
Why have so few businesses decided what AI does with their site?
Plenty of businesses are in Teresa's position. Someone built the website years ago, nobody has ever opened the robots.txt file, and decisions about AI have been made by default. Until now, deciding was a chore, too: you had to keep track of every company's bots and write a rule for each one.
And three different things get mixed up: your site showing up on Google, an assistant using your page as a source for an answer with a link, and your text and photos being used to train a model. Each is governed by its own rules, and confusing them leads to decisions nobody meant to make.
What is at stake if you do not decide?
If you say nothing, other people decide how your content is used. For a business whose product is that very content, such as recipes, courses, guides or photos, that is a lot to leave to chance.
Going too far the other way has a cost as well. Google's documentation says Google-Extended does not affect a site's inclusion in its search engine and is not used for ranking, so opting out of training will not take you off Google. But in its announcement, Google adds that sites which specifically allow Google-Extended can appear, with a link, in Gemini app answers, and that using the shared signal to opt out of training, without a separate Google-Extended rule, will count as blocking it. Shutting everything off without thinking may keep you out of those answers.
One more warning: robots.txt works on good faith. As heise notes, it is no substitute for a technical access restriction, and only the providers that choose to respect it will do so.
How can you get your site ready before 2027?
There is no need to wait for the shared signal to go live before sorting out your decision. These steps work now:
- Take stock of your content and split it into two piles: your shop window (services, prices, contact details, press) and your product (courses, downloadable guides, paid photos).
- For each part, decide whether you accept it being used to train models and whether you want to appear as a source in assistants. They are two separate questions.
- Open your current robots.txt at yourdomain.com/robots.txt and check which bots it mentions and what it allows them to do.
- Put anything that is genuinely paid for behind a username and password: robots.txt is a request, not a lock.
- Make a note to review it once Google and the other providers confirm they read the shared signal, because the proposal is still under discussion.
For Teresa, the outcome could look like this: the courses page and contact page open to everyone; the free recipes with her training decision written down; the members' area behind its password, as it already is. Three decisions, each with its reason.
What we do at digizone with your website content
At digizone we help businesses make technology decisions with a clear rationale through our technology consulting: we review what your website publishes and what it tells search engines and assistants, and we bring it into line with what you want to protect and what you want to show.
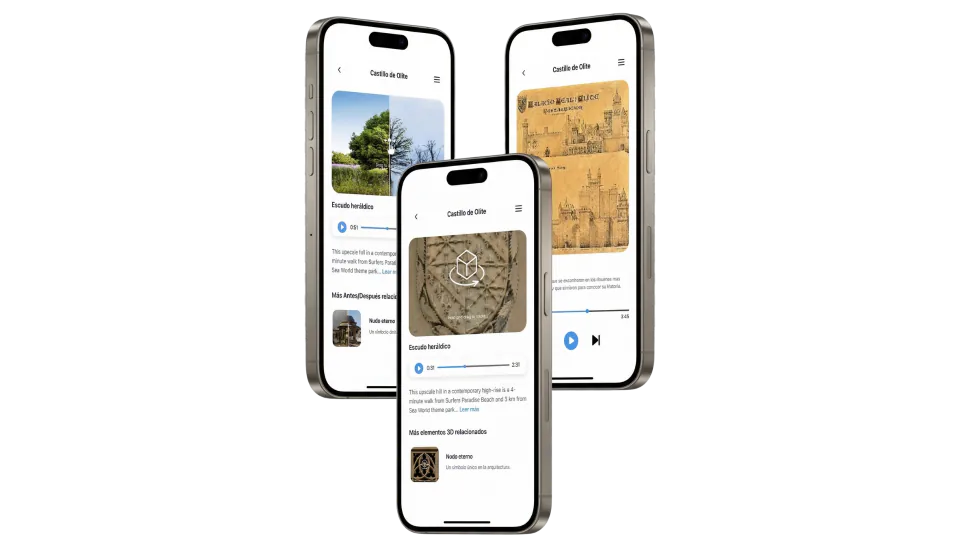
We see it often in projects where content is the heart of the business. For CulturApp we built a web app that turns places of interest into tours with text, images, audio, video and even 3D elements, with a control panel where managers and collaborators create their own content. Managing free and paid access was part of the brief from the start, and separating what is open from what is reserved is the same question that now needs asking about AI.
Start with three rows
You do not need a twenty-page AI policy. At Teresa's school, the first version would be a table with three rows, recipes, courses and members' area, with what she allows and what she does not next to each. With that, whoever looks after her site can write today's provider-by-provider rules and have the shared rule worked out for when it arrives. If she adds a downloadable recipe book next month, she adds a row.
If you would like to see how it would work for you, our free workshop, in Spanish, walks through it step by step.
Frequently asked questions
What is robots.txt and where is it?
It is a text file that sits at the root of a website, at yourdomain.com/robots.txt, and gives instructions to the bots that crawl it: search engines, AI companies' crawlers and others. Each block says which bot it is addressing and which folders it may or may not visit. You can open it in any browser; changing it requires access to the server or the site's content management system.
If I block AI training, will I disappear from Google?
Not because of that. According to Google's documentation, Google-Extended, the rule used to opt out of training its Gemini models, does not affect a site's inclusion in Google Search and is not used for ranking. Google does explain that sites which specifically allow it can appear, with a link, in Gemini app answers, so blocking it may keep you out of those.
When will the shared AI training signal start working?
Google says it aims to support it alongside other AI providers in 2027, and its documentation mentions early 2027. The signal comes from an individual draft submitted to the IETF on 30 October 2026, which is not yet a standard. In the meantime, each provider's own rules still apply, such as GPTBot, ClaudeBot or Google-Extended, among others.
Does robots.txt actually stop my content being used?
It is not a lock. It expresses a preference that is respected by the providers that choose to do so, and the shared-signal draft accepts that a private agreement may override it. Anything genuinely paid for or confidential should sit behind a username and password, which is a technical restriction and does not rely on anyone's good faith.
Should I block AI training across my whole site?
It depends on what you publish. The sensible approach is to separate your shop window (services, prices, contact details, press), which you want to circulate, from your product (courses, guides, paid photos), which is what you sell. The shared signal lets you say no in general and open specific folders, or the other way round, so the decision can be made in parts rather than all or nothing.
Sources
About digizone
digizone is a custom software development company founded in 2019, with offices in Barcelona and Cartagena (Spain). We design and build mobile apps, web applications, CRM/ERP systems and AI automation for startups, SMEs and enterprises. Meet the team
Other articles
Don't get left behind: if you want to keep up to date with the fast-moving technology sector, take a look at the following articles:
AI training for employees: what holds small firms back
The Bank of Spain finds a lack of skilled staff is the biggest barrier to AI, yet few small firms plan to train their teams. How to start with the people you have.
Read more »
PHP vulnerability: what to check if you use WordPress
PHP has fixed two critical flaws, found with the help of AI, that let attackers take over a website. What to ask your hosting provider today if you use WordPress.
Read more »
AI shopping agents: your shop has to be readable too
Walmart is opening its store to AI shopping agents that search and buy for customers. What it means for a small online shop and what to check on your site.
Read more »Contact us
Do you have any questions? Would you like to schedule a call or a meeting? We would be happy to address any concerns and start working with you. The perfect digital solution for your business is just around the corner.
Subscribe to the newsletter
Discover the digital future by subscribing to our exclusive newsletter! Stay updated on the latest trends and developments in the world of technology. Don't miss the chance to be the first to learn about the innovations that are transforming the present! Subscribe now.